AI Spend & Token Analytics
Every token accounted for. Every lane priced. Zero tokens spent on the accounting.
What was getting in the way.
Teams running AI agents can't see where the money goes. Token spend hides inside dozens of parallel agent sessions, a surprise "out of tokens" morning halts every workflow at once with no explanation, per-task cost is invisible — and the obvious fix, asking the AI to analyze its own usage, burns more of exactly the thing you're trying to measure.
Context
The agency's own multi-agent operation — the same environment that runs client work, instrumented before offering it outward.
How the work runs.
- 01
Read the source of truth
The analytics read the agent platform's own transcript store directly, read-only. No exports, no third-party dashboard.
- 02
Price every turn
Per-turn cost and input/output/cache token counts are aggregated per session and per workflow lane.
- 03
Rank the spend
A leaderboard prints total spend, the per-day trend, and the top lanes by cost with turns and output volume.
- 04
Flag the waste
Rules flag lanes with abnormal cost-per-turn (the signature of a bloated context dragging cache reads) and prescribe the one-step fix: reset that lane.
- 05
Triage hard-fails
A sudden day-spike near the account's rate limits explains simultaneous "out of tokens" failures across workflows; the report points to the provider's billing console for confirmation.
- 06
Guard before the spend
Expensive operations trigger a tiered warning first: estimated cost, a choice of depth (quick / standard / deep), and the actual cost disclosed after.
- 07
Zero-token accounting
The analysis itself is plain database reads; measuring the spend never adds to it.
Evidence from the workflow.
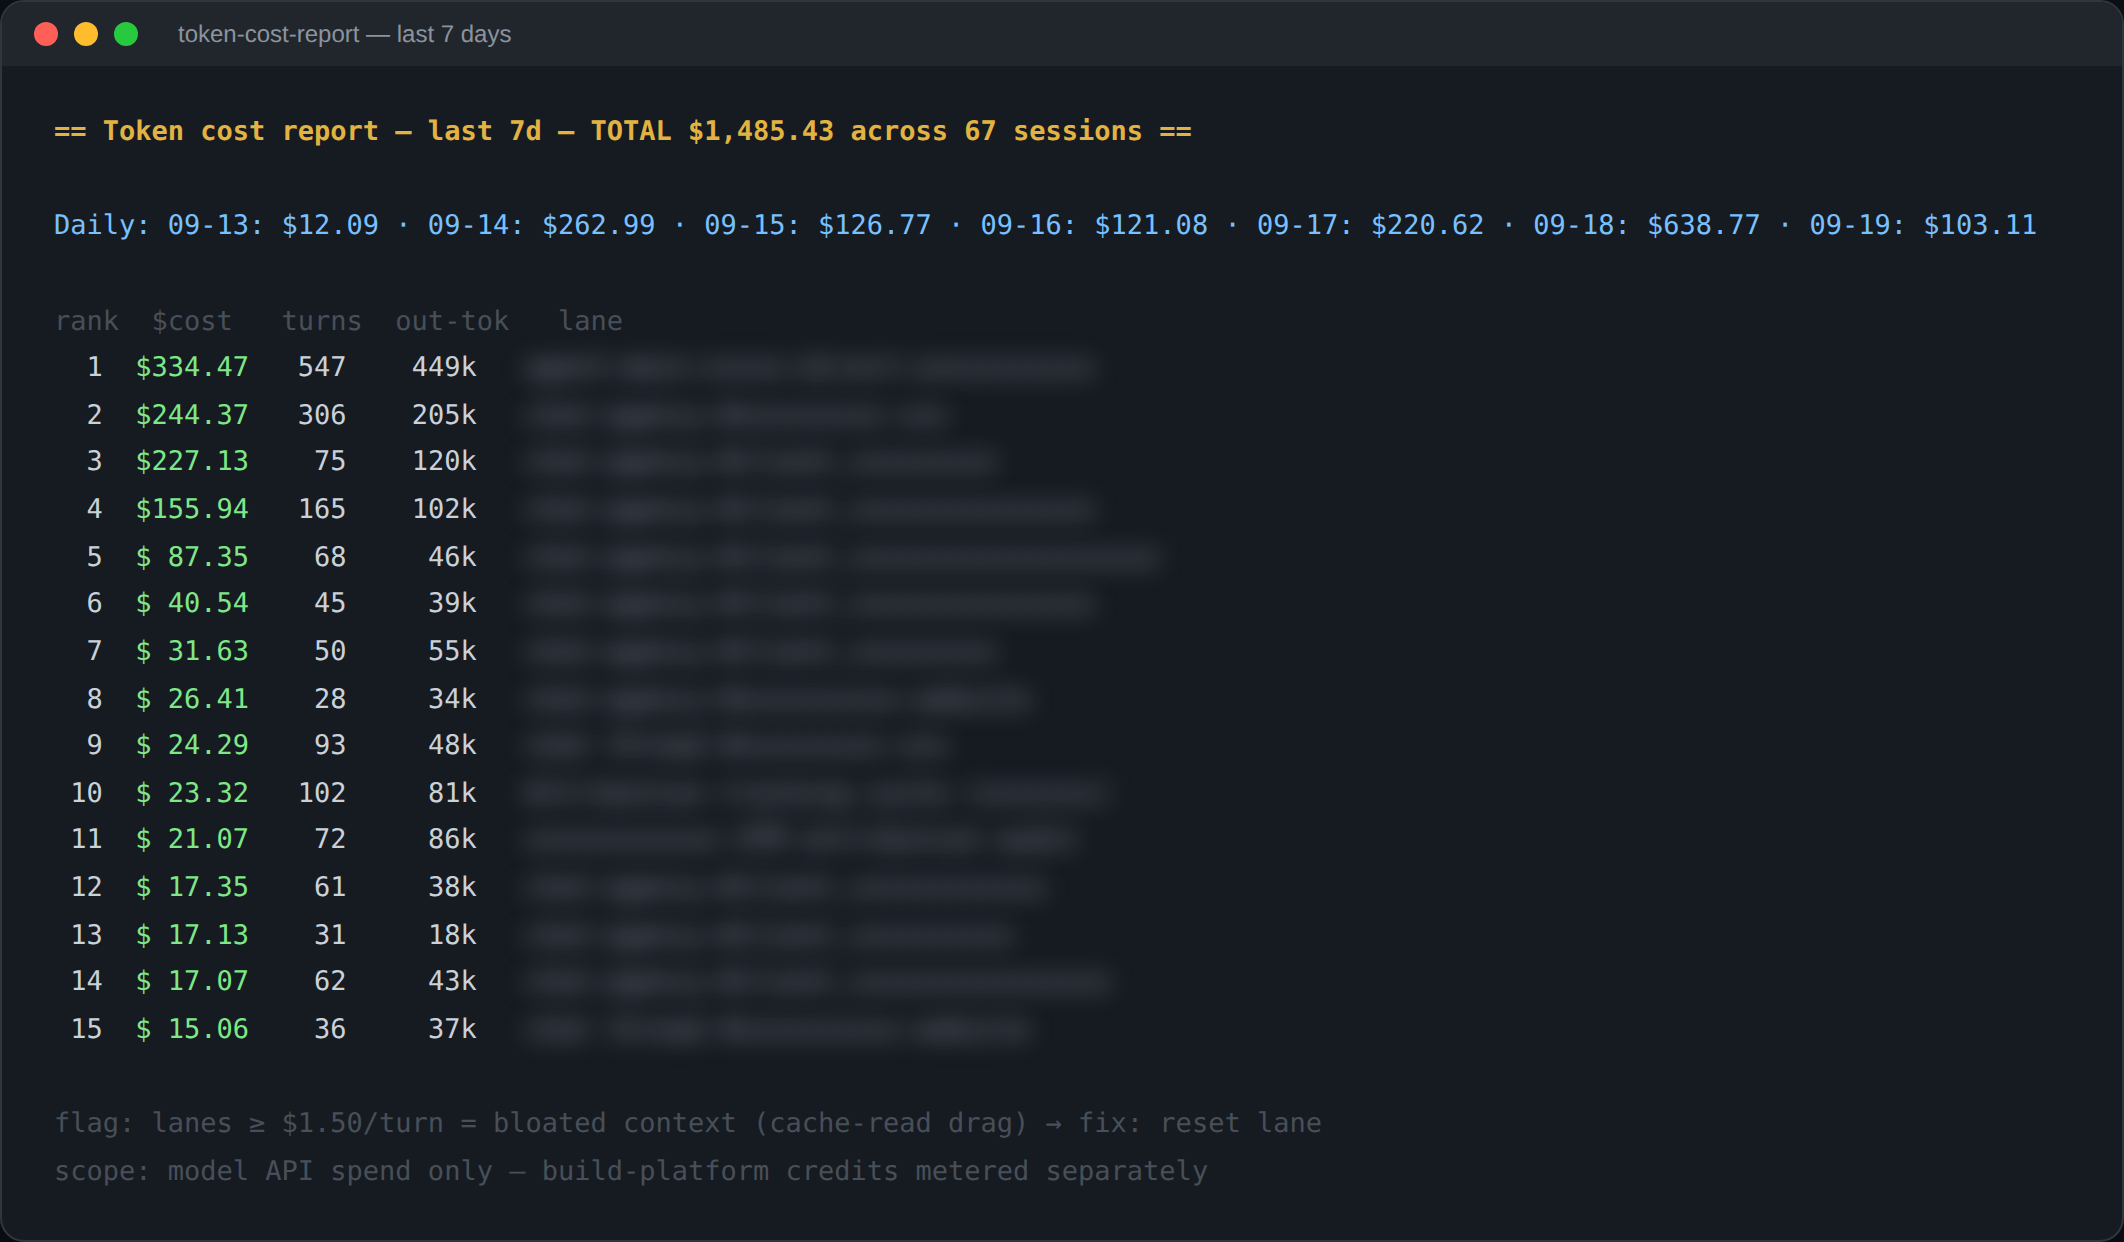
Each system has a role.
Record of Truth — per-turn usage & cost
Agent platform session store
Signal — rate limits & provider-record reconciliation
Model provider billing
Action — reports and warnings where the team works
Team chat
Action — weekly digests, next phase
Scheduler
Why this is Copilot.
Helps a person work faster. You ask, it answers. All actions belong to a human.
- 01
Read-only against the live store — the analytics can never alter agent history. Transcript contents never leave the environment; only aggregates are reported. Spend thresholds and flag rules are human-tunable. Expensive operations proceed only after human approval of the cost warning.
Impact / Outcomes
"What's burning tokens?" answered in seconds from the platform's own records — with zero model tokens spent on the answer
High cost-per-turn lanes caught with a prescribed one-step fix, keeping multi-agent context costs bounded
"Out of tokens" mornings turned from mystery outages into a two-minute diagnosis
Find where a workflow like this fits.
Start with the systems, work, constraints, and authority already present in your operation.